Fikra × UwenzAi: Bringing Kenyan AI Inference to the UwenzAi LLM-Gateway
Fikra is now available through the UwenzAi LLM-Gateway, giving users access to models from a Kenyan inference provider alongside providers hosted outside the region.
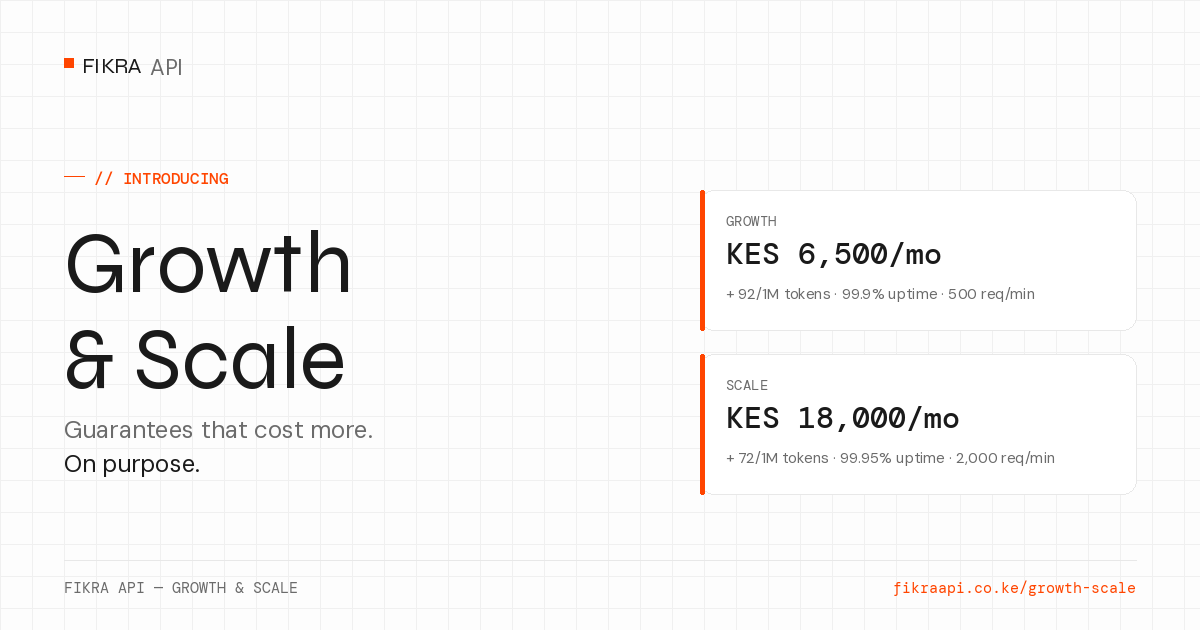
Fikra API gives companies production-ready access to AI inference without forcing them into enterprise contracts. Start experimenting for $1, scale to reserved throughput when it matters.
Move from pay-as-you-go to reserved capacity without changing a single line of code.
Starting at $1
$50/mo
~ KES 6,500/mo platform fee
For companies running real AI products in production.
$138/mo
~ KES 18,000/mo platform fee
When your AI workload cannot afford to be treated like an experiment.
Multiple providers. Changing models. Increasing traffic. Rate limits. Unpredictable costs. Building a product is hard enough without also having to engineer and maintain a robust inference layer.
Fikra gives your team a single AI inference layer so you can focus on the product above it.
You don't need Growth because you're big. You need Growth because your AI product is real. You can't afford to treat inference like an experiment anymore.
Your AI infrastructure now directly affects your customers. Downtime is a business issue, not a technical curiosity.
Shared limits are no longer acceptable for production workloads. You need guaranteed capacity when demand spikes.
You need an explicit SLA and someone accountable when something breaks.
Move your existing AI workload to Fikra without rebuilding your infrastructure. Fikra API is fully OpenAI-compatible. Any SDK, any language. Point your base URL to our endpoint and everything else stays the same.
Already running in production? Move that workload to Growth.
99.9% SLA · 500 RPM reserved · 48h support
Explore Growth →import openai # Change just this line client = openai.OpenAI( base_url="https://api.fikraapi.co.ke/v1", api_key="your_fikra_key" ) response = client.chat.completions.create( model="fikra-fast-8b", messages=[{ "role": "user", "content": "Analyze this dataset." }] )
Access multiple AI models and providers without building the routing, failover, and abstraction logic yourself.
Reserved throughput and explicit uptime SLAs that allow you to guarantee reliability to your own customers.
Get company-grade infrastructure and direct support without entering a heavyweight, multi-month enterprise procurement process.
Start self-serve. Move to Growth. Move to Scale. Keep the exact same API and integration as your business expands.
Your customers depend entirely on your AI features. Your traffic is growing rapidly. An inference outage is now a severe business problem, not just an inconvenience.
$138/mo
~ KES 18,000/mo platform fee
Ship production AI without spending your limited engineering capacity building and maintaining a complex inference layer from scratch.
Add generative AI features to your core product without making your team responsible for managing multiple inference providers and failover limits.
Run custom AI workloads for multiple clients through a single, predictable production infrastructure layer.
Get guaranteed reserved capacity, SLAs, and operational support without having to negotiate an enterprise procurement contract.
Comprehensive guides on endpoints, streaming, function calling, and RAG architectures.
View Docs →Transparent metrics on API latency, model availability, and historical uptime.
System Status →Our proprietary 1.58-bit ternary weight architecture optimized for edge environments.
Read the paper →Not ready? Start self-serve from $1.
Company news, technical research, and practical writing from the Fikra team.
Fikra is now available through the UwenzAi LLM-Gateway, giving users access to models from a Kenyan inference provider alongside providers hosted outside the region.
An author-conducted evaluation of four language-model configurations served through the Fikra API, using a frozen 500-task suite to examine reasoning, mathematics, instruction following, function calling, execution coverage, latency, and evaluation methodology.
Two new tiers sit above self-serve - not because we discounted anything, but because uptime, reserved throughput, and real support response times are worth paying for honestly.
We are open-sourcing Fikra Nano 1B, a revolutionary ternary weight model optimized for extreme low-resource environments. Learn how bypassing floating-point math enables high-throughput inference without the massive VRAM tax.
Tired of credit card declines and aggressive $20 minimum top-ups? Here is an honest, benchmarked breakdown of the top inference APIs built for regional access.
When your AI systems become business-critical, Fikra provides a path beyond standard API access — from production infrastructure to governed enterprise deployments.
Enterprise engagements for organizations deploying AI across production workflows, teams, and business-critical systems.
A focused enterprise pilot for deploying an AI agent into a defined business workflow, with the rules, controls, and governance required to operate it responsibly.